Taylor Fang

Designing for the dual reader experience
Docs communicate a product and its scaffolding. They should help a user build a mental model of the product and how it works, guiding them along an intuitive flow and answering questions along the way. Docs must simplify concepts for new users and reveal complexity as the user advances.
There’s also a new reader. Agents are rapidly overtaking human users as first-class citizens, and they need specialised architecture to discover, read, and parse docs.
Our docs grew organically as our platform expanded to support new frameworks and integrations. But structure, ordering, and language started to drift.
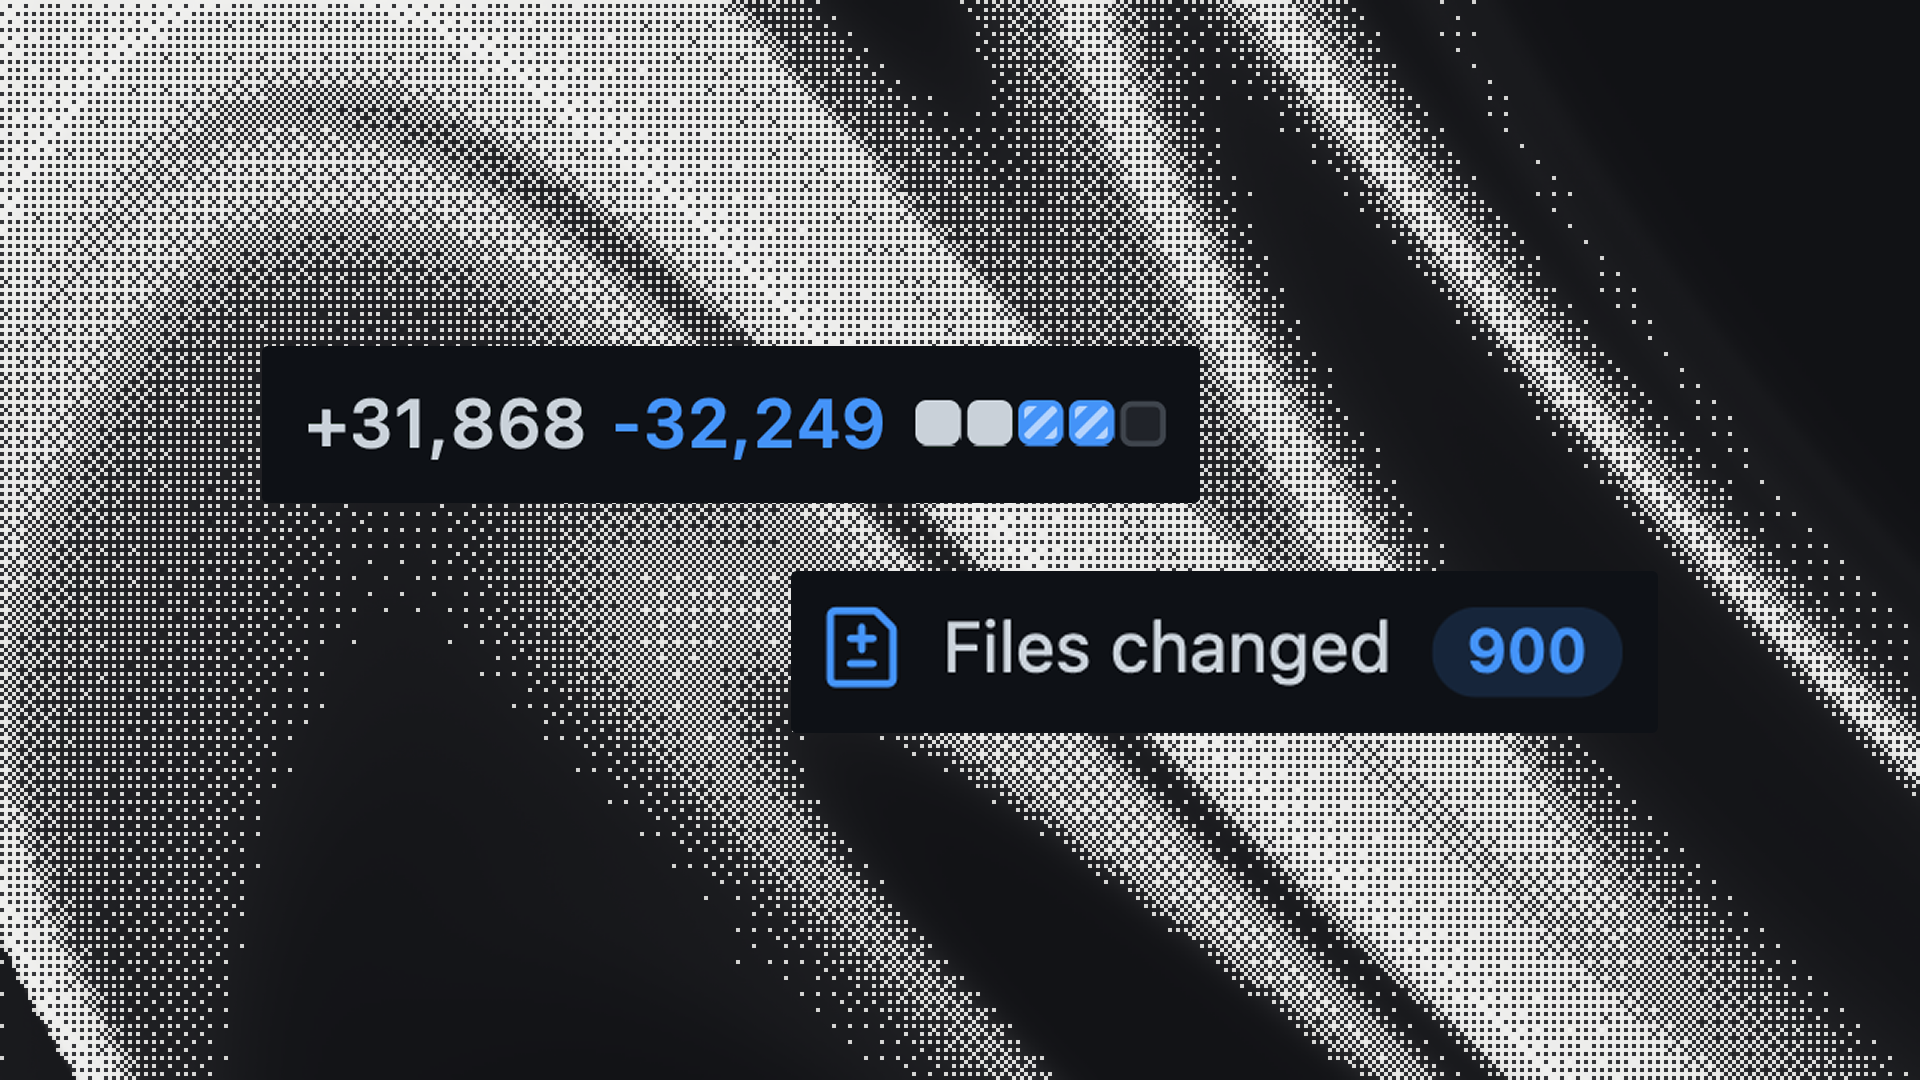
We decided to rebuild our docs from scratch with a deliberate eye to the reader experience for both humans and agents. The initial refactor touched 900 files (+31,868 / −32,249 lines). We created a 13,000-word style guide with rules for audience, page anatomy, and style and grammar. The docs are now maintained by a daily cloud agent that lints against the style guide.
For agent readability, we also serve llms.txt and llms-full.txt to index the site, and serve every docs page as raw Markdown by appending .md to its URL. We ship a docs page for coding agents with a drop-in AGENTS.md that tells an agent how to set up, use, and translate correctly, alongside our MCP server and machine-readable OpenAPI spec.
This post covers the changes we made and our learnings.
Inspirations
We researched and took inspiration from best practices and developer docs we admire:
- Lee Robinson’s writing on documentation. “Keep the first-time experience simple and slowly reveal complexity.” His ten principles include: fast, readable, AI-native, polished, responsive. And localised, of course. (We actually worked with Lee to localise Cursor’s docs!)
- Fuma Nama’s writing on documentation. He recommends a simple writing style and building in more logical structure with bolding, headings, hyperlinks, lists and tables. Fuma also argues that navigation can matter more than content for the reader experience. (Read more about Fuma’s philosophy in our interview.)
- Devin Logan’s writing on agent-ready documentation. Devin writes that the new baseline is users accessing docs through agents. She outlines steps for AI readability: on the content side, content needs to explain systems and share executable steps; on the platform side, pages need to be findable and stripped down for agents.
- We looked closely at developer docs we love: Linear for clarity and simplicity, Replicate for clear hierarchical navigation, shadcn/ui for beautiful design, Next.js for developer language and community features, Convex for delightful visuals, Stripe for embedded functionality, and many others.
User journeys
We restructured pages and language around what the user wants to achieve, as opposed to simply describing technical capabilities. Every section follows a consistent spine: Quickstart, Guides, and Reference.
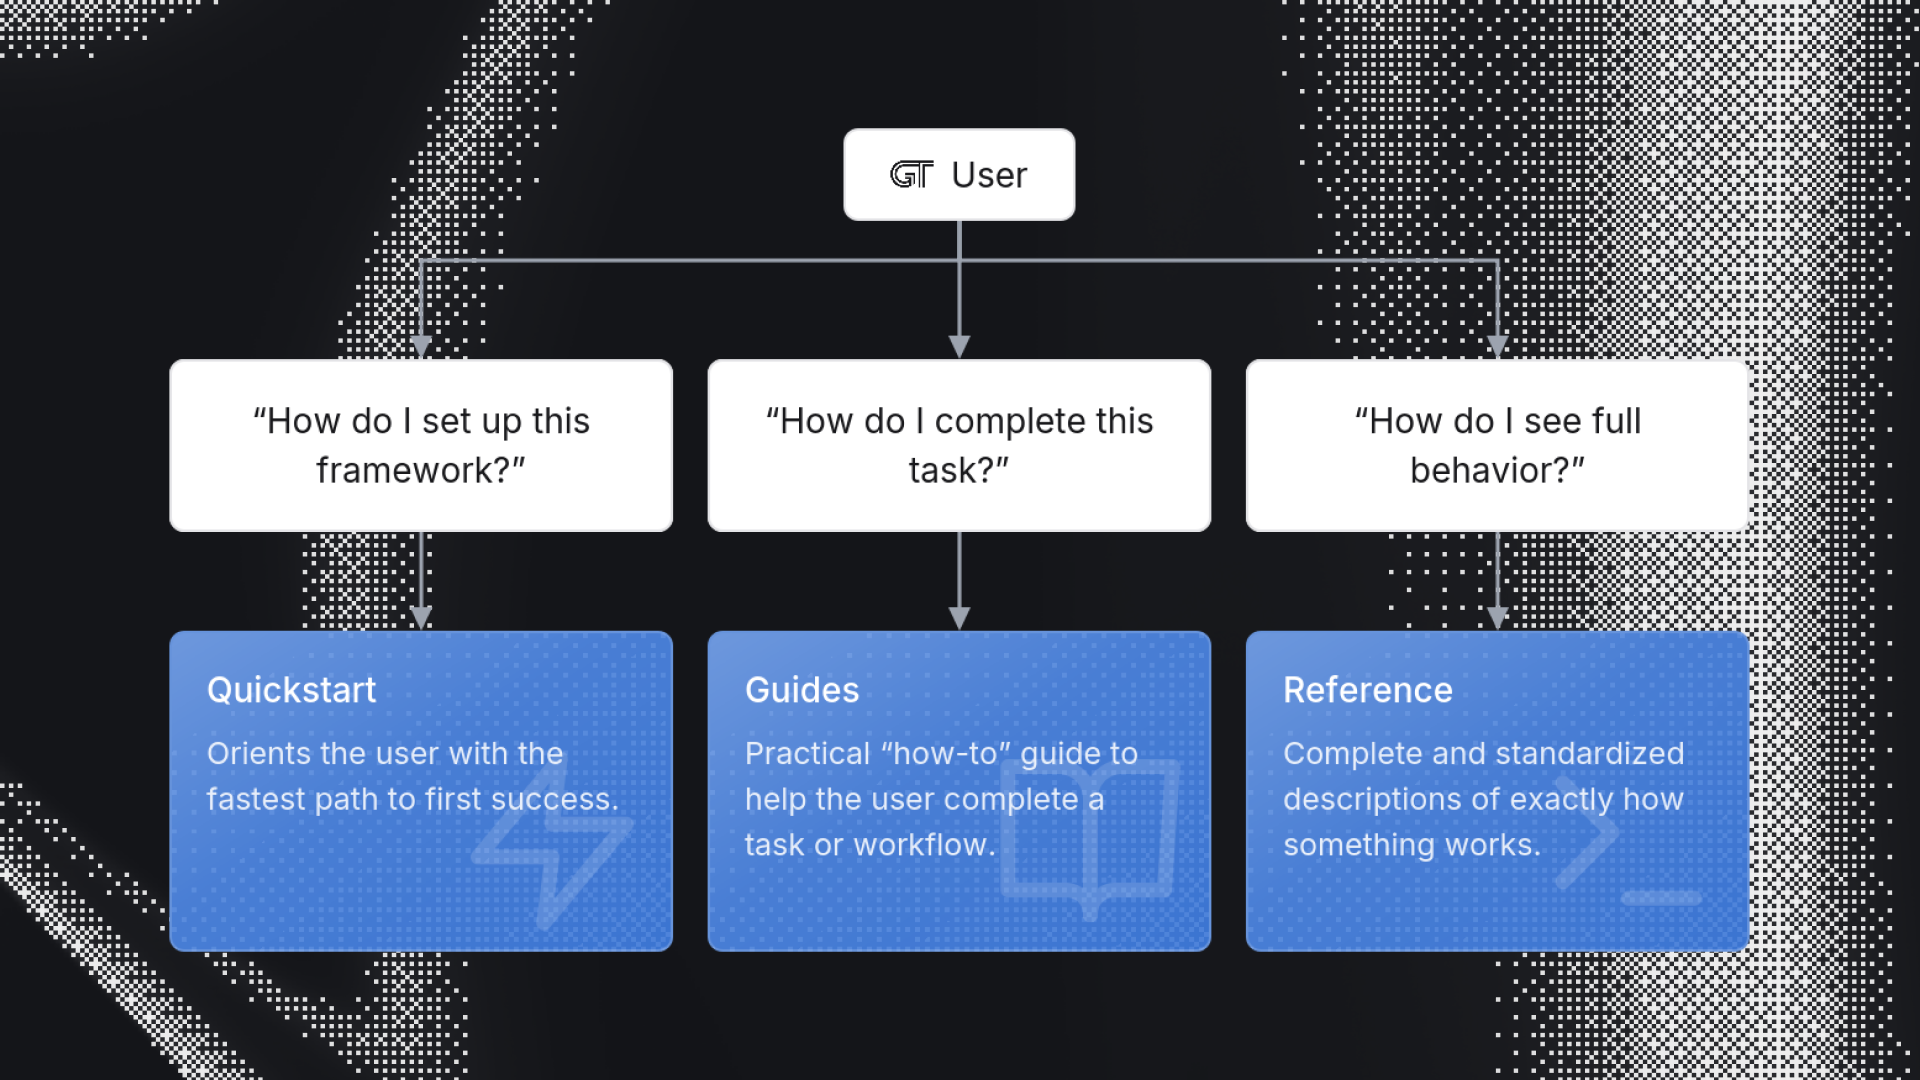
Guides are titled as gerunds and jobs to be done, like “Reviewing and editing translations” or “Handling plurals and branches”. A new user trying to complete a workflow doesn’t need to work out which reference term to search for; they can simply search for the action they want to take.
A nice secondary effect is that our docs guides themselves rank highly on SEO, including as the top Google result for searches like “React managing locales”, “React translating jsx”, “Configuring a Vite SPA i18n”, “React plurals and branches”, “Translating rrweb”, and many others.
The docs site itself is built on Fumadocs, whose creator we recently interviewed about his philosophy of a beautiful, composable reader experience.
Logical and intuitive flow
Docs should help the user build a mental model of the product and how it works. To this end, an intuitive flow in both navigation and on each page is important. Ordering should be deliberate and meaningful, grouped logically and sequenced in the order in which a reader is likely to perform an action. The goal is to follow the learning curve, so beginners can easily build the correct context, with complexity and customisation revealed as users read and learn more deeply. An intuitive flow should feel invisible.
a) Structure. Our docs structure and ordering are enforced in CI, with a check that pins top-level sections so a new page slots into the existing information architecture.
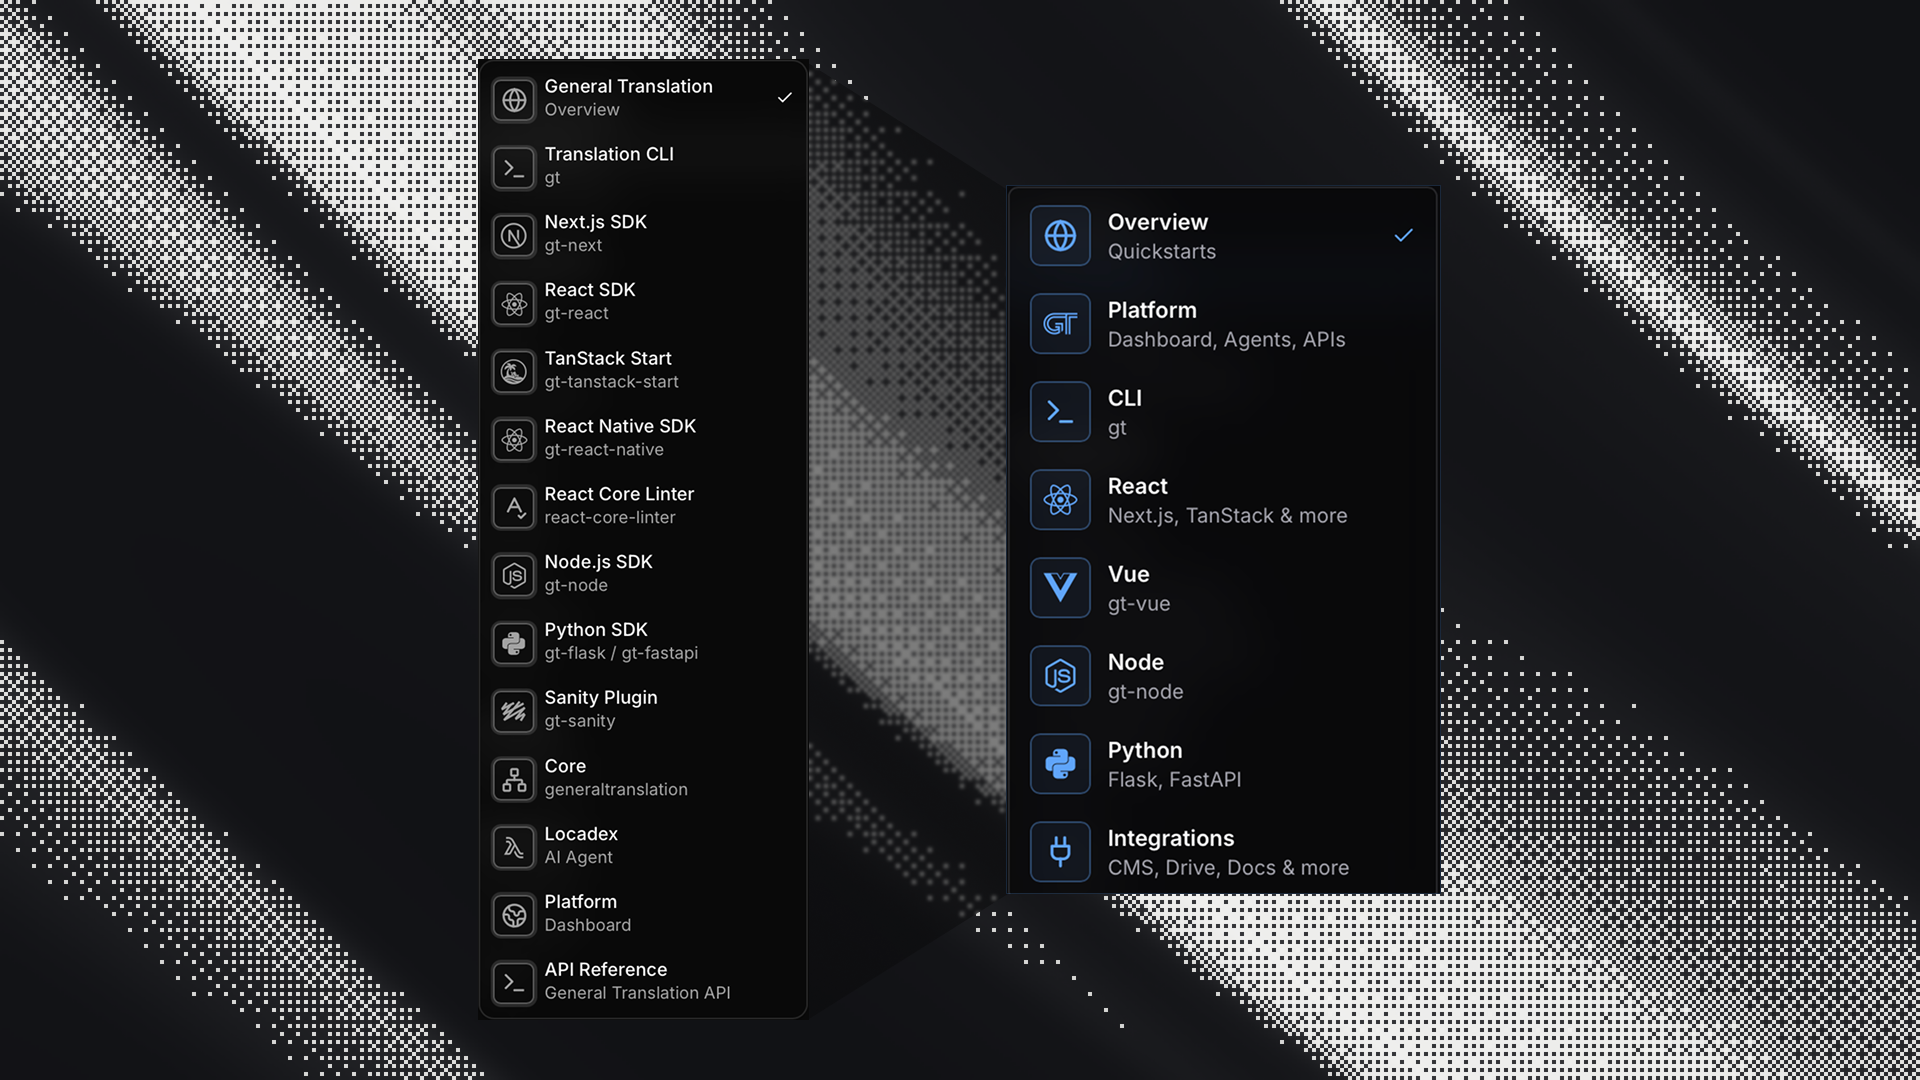
b) Related pages. Each page guides users to next steps, with related links updated by logical proximity. Quickstart leads to the four most commonly viewed Guide pages, and each Guide page leads to related Guides or References. Links live in the frontmatter rather than body text so the build can check targets against the page tree.
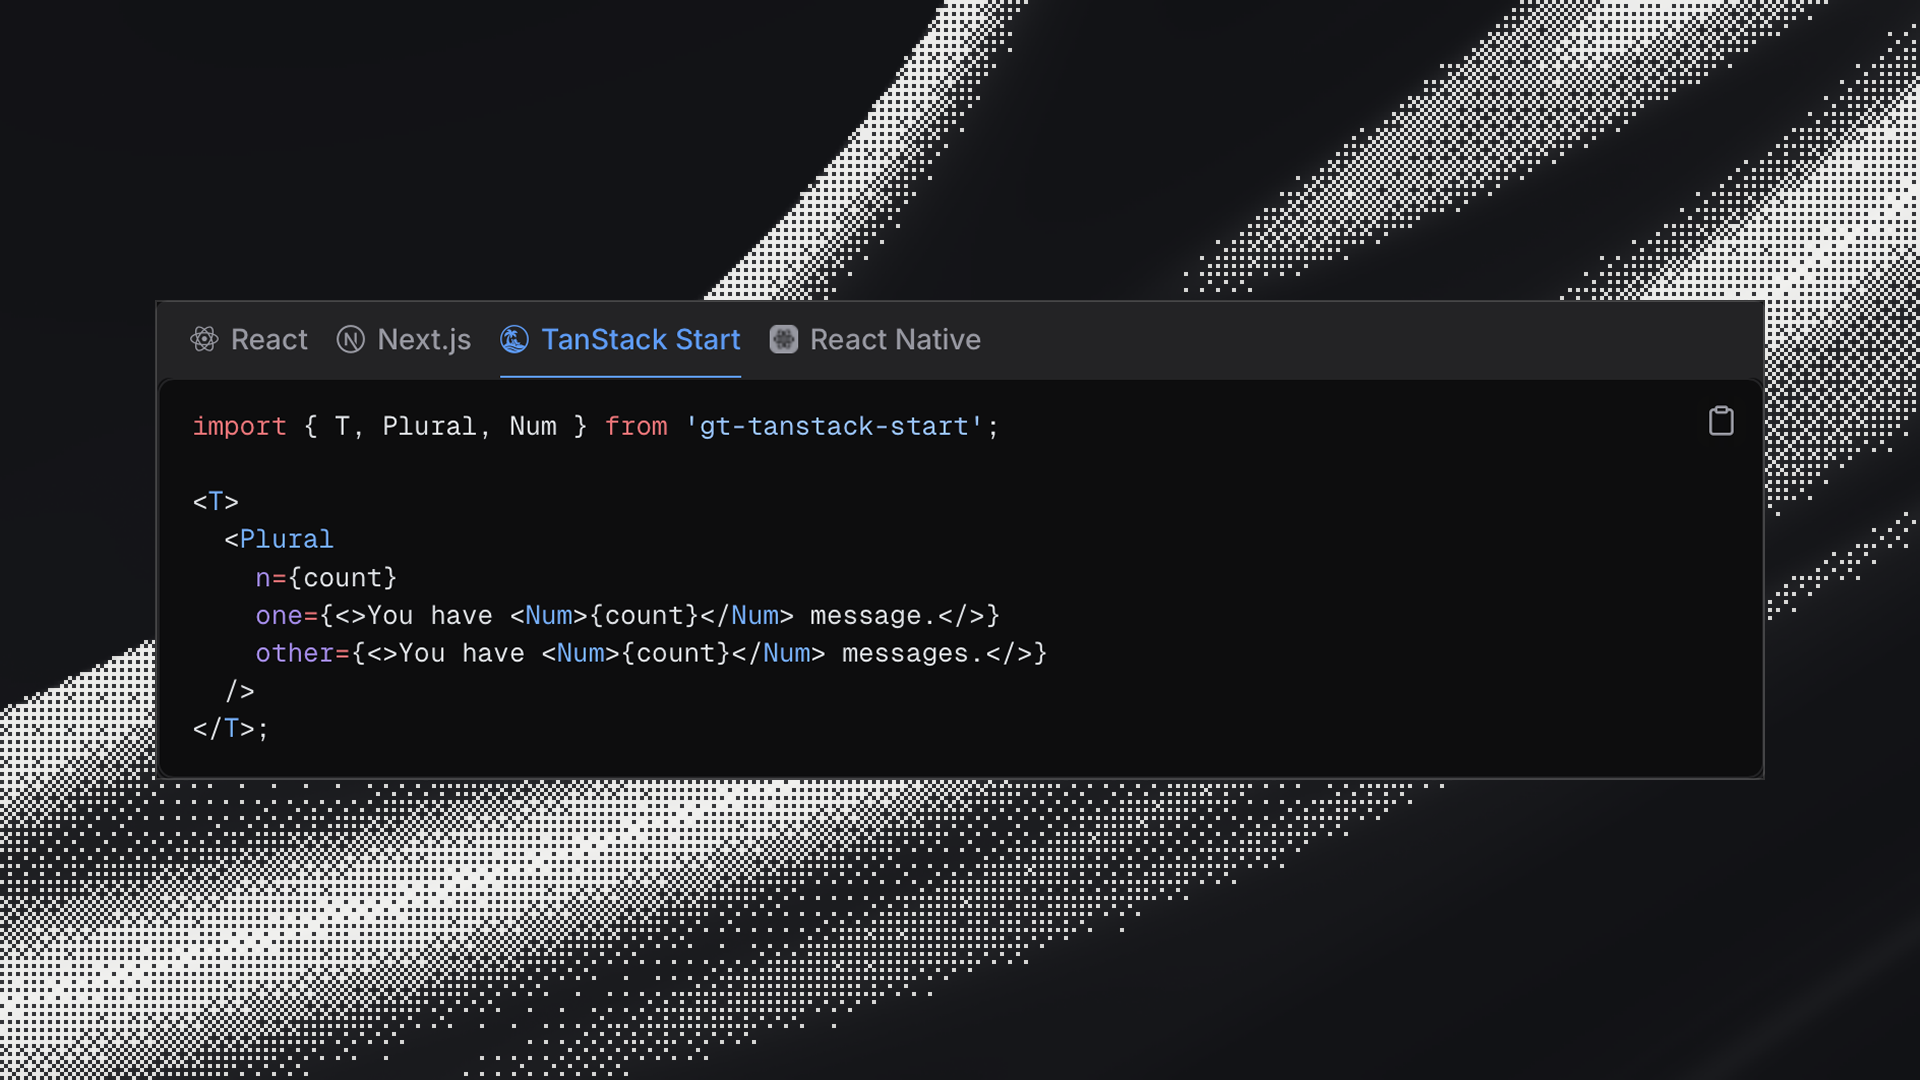
c) User selections. The docs site remembers user selections, displaying content automatically in a user’s last-chosen language and theme. The code blocks also automatically preserve the user-selected tab for framework (React vs. Next.js vs. TanStack Start vs. React Native) and package manager (npm vs. yarn vs. bun vs. pnpm).
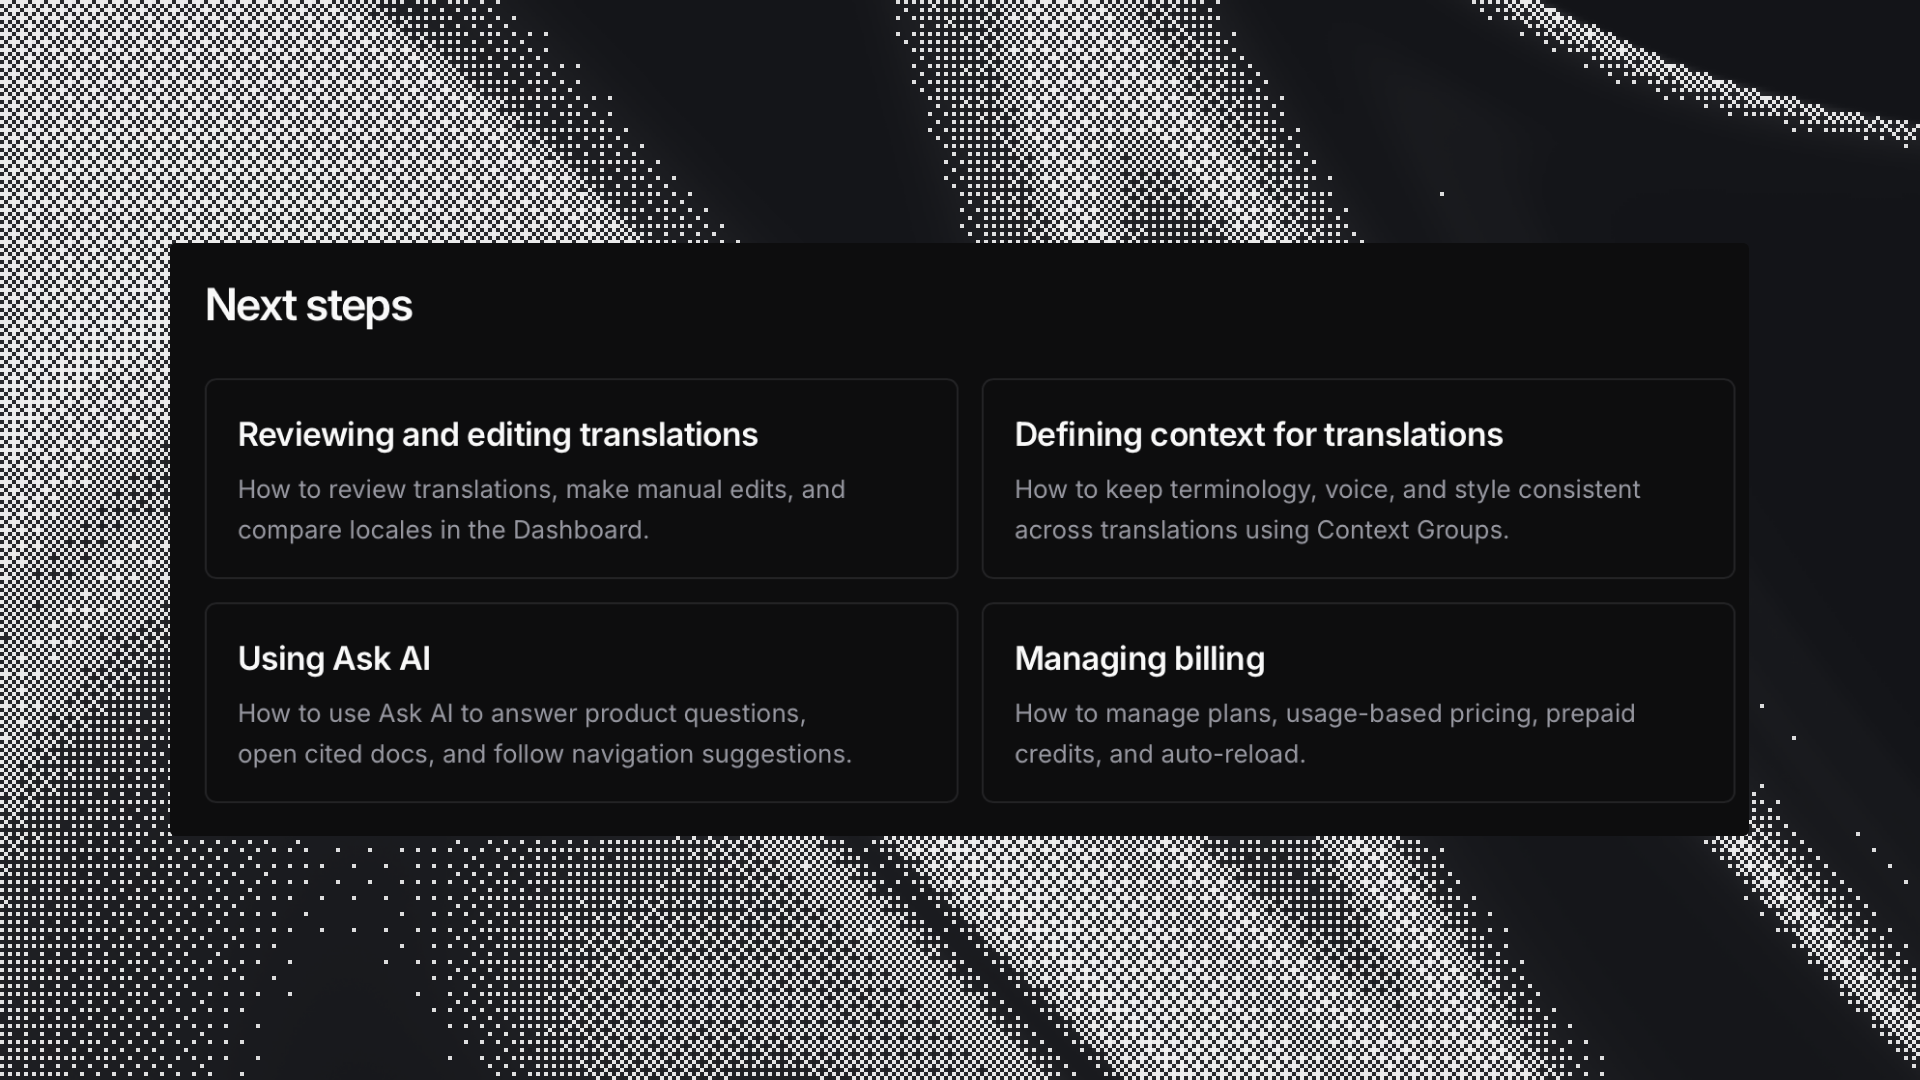
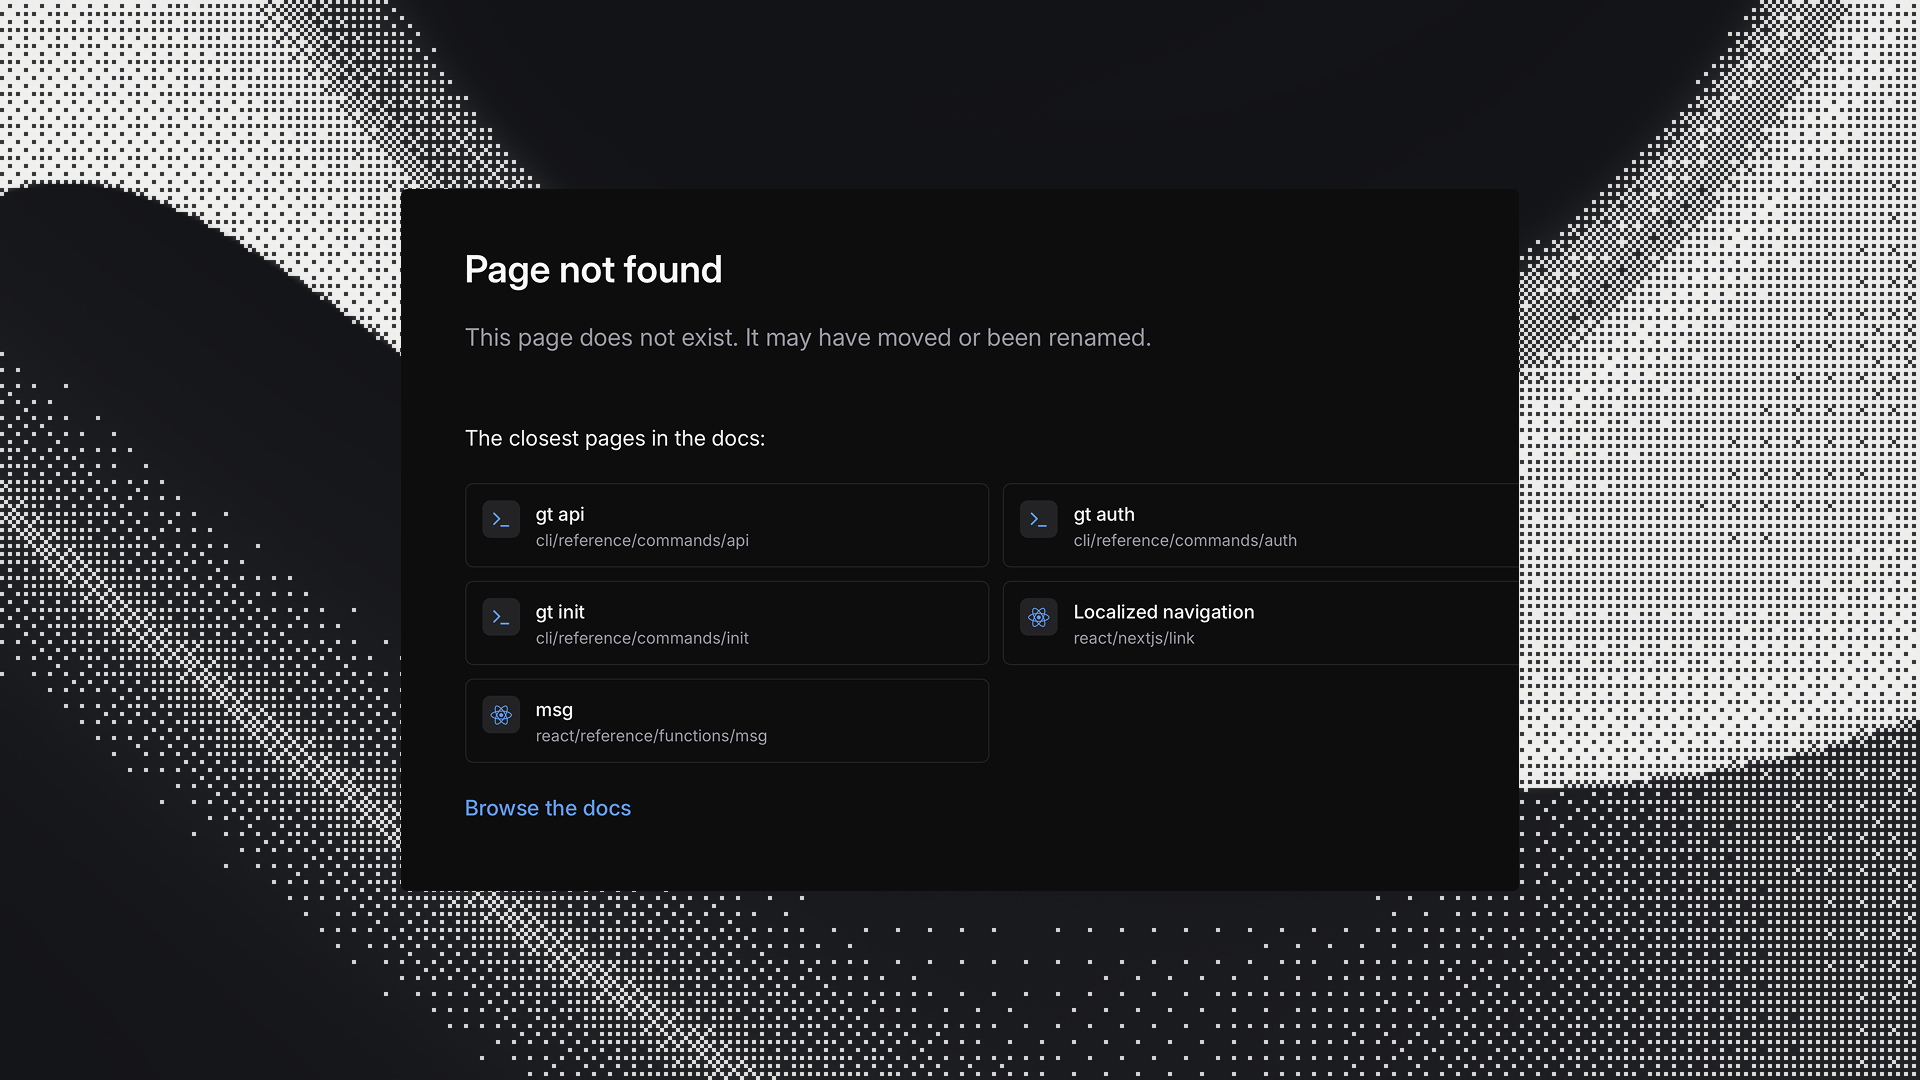
d) Link paths. Our link paths are another small detail: slugs are not just the page title, but the fewest words that are still unambiguous. Links and heading anchors stay the same even if wording or content changes. We’ve also built in a catch system for misspelled URLs to redirect to the nearest match or a special 404 with the five closest pages.
Simple language
Given the many different user personas on our platform, the language itself focuses on simplicity and clarity. Each page orients the reader first with what it covers and when to use it, before diving into how it works. Each section is also a focused and self-contained chunk, which, as it turns out, is easier for both humans and agents to read.
Each page is directed at and tailored for a specific audience. From our docs style guide:
Audience
Write for the reader of the specific page, and match depth and vocabulary to them:
- Technical, developer-facing pages. Readers are developers integrating the SDK, CLI, or API. Be precise about types, parameters, headers, defaults, and error behaviour; show runnable examples. Ensure documentation is also machine-readable by LLMs and agents.
- Nontechnical, product-facing pages: Dashboard and Locadex. Readers are localisation managers, translators, and PMs working in the Dashboard UI. Lead with outcomes and UI actions; explain concepts in plain language.
Clarity rules for every audience:
Lead with what it is and why before how.
One idea per sentence; prefer short sentences.
Define a term the first time it appears, and expand acronyms on first use.
Do not use a concept, product term, or setting before it has been introduced.
Avoid unexplained jargon. If a term is unavoidable and too complex to explain in a sentence, link to where it is defined.
We also wrote pages for specific user personas. For users new to localisation, the Key concepts page explains core concepts in basic language: internationalisation, localisation, translation, locales, and context. For users primarily using agents, the Using coding agents page points agents at our machine-readable docs, MCP server, and drop-in AGENTS.md guide (more on this below).
Designing for agents to read
As multiple sources have written about, agents now comprise a majority of docs readers. So LLM-friendliness is a first-class priority. Many of the same readability and structural principles apply to content for both humans and agents; however, agents need specialised discovery, retrieval, and tool access capabilities.
We’ve designed our agent-readiness with Vercel’s Agent Readability spec and the AFdocs spec. These two specifications address key questions based on how AI agents find and parse content. Can agents discover the docs pages and navigate what they cover? Can they read clean markdown content that fits in a context window? Can they search, fetch, and use the correct AI tools?
Key parts of our implementation include:
llms.txt: an index of the docs following the llmstxt.org standard, with additional layers:llms-index.txt(every page),llms-scope.txt/<section>(per-section indexes), andllms-full.txt(the full corpus for tools that can load a larger context)sitemap.xmlandsitemap.md: machine-readable maps of every page- Raw Markdown for every page: append
.mdor.mdxto any docs URL. Recognised AI crawlers and agents that sendAccept: text/markdownget Markdown automatically - An MCP (Model Context Protocol) server: the
@generaltranslation/mcpnpm package for local stdio use, a hosted endpoint athttps://mcp.gtx.dev(streamable HTTP, with an SSE variant), and a project-scoped endpoint athttps://api.gtx.dev/mcpauthenticated with an API key - A machine-readable OpenAPI spec at
/openapi.json(and/openapi.yaml) linked from every endpoint reference page - Content structured in chunks for RAG (retrieval-augmented generation), with each section containing a complete thought and consistent heading hierarchies
- A permissive
robots.txt: AI crawlers are never blocked
Process, maintenance, and style guide
The process of rolling out this massive refactor of our docs was a collaboration between one human writer (myself!) and various AI tools, with input from the rest of the team. Our principle is to use human writing and judgement to provide understanding of content, meaning, and logical flow, translate learnings into a strict and comprehensive style guide, and use AI to scale the style guide and stay in sync with our codebase updates.
I first ran a comprehensive discovery pass to return an inventory of all existing docs content across 900 pages and 117,000+ words of prose. Given the index of this raw material, I restructured content based on a hand-written map: which high-level sections we needed, how the frameworks should be grouped and ordered, and the purpose of each page. I wrote and edited representative pages in each section to incorporate our principles of clarity, simplicity, and supporting the user journey. The handwritten part of the process took over a month of focused work. The quickstarts in particular required a lot of testing, and our i18n library engineers made significant edits.
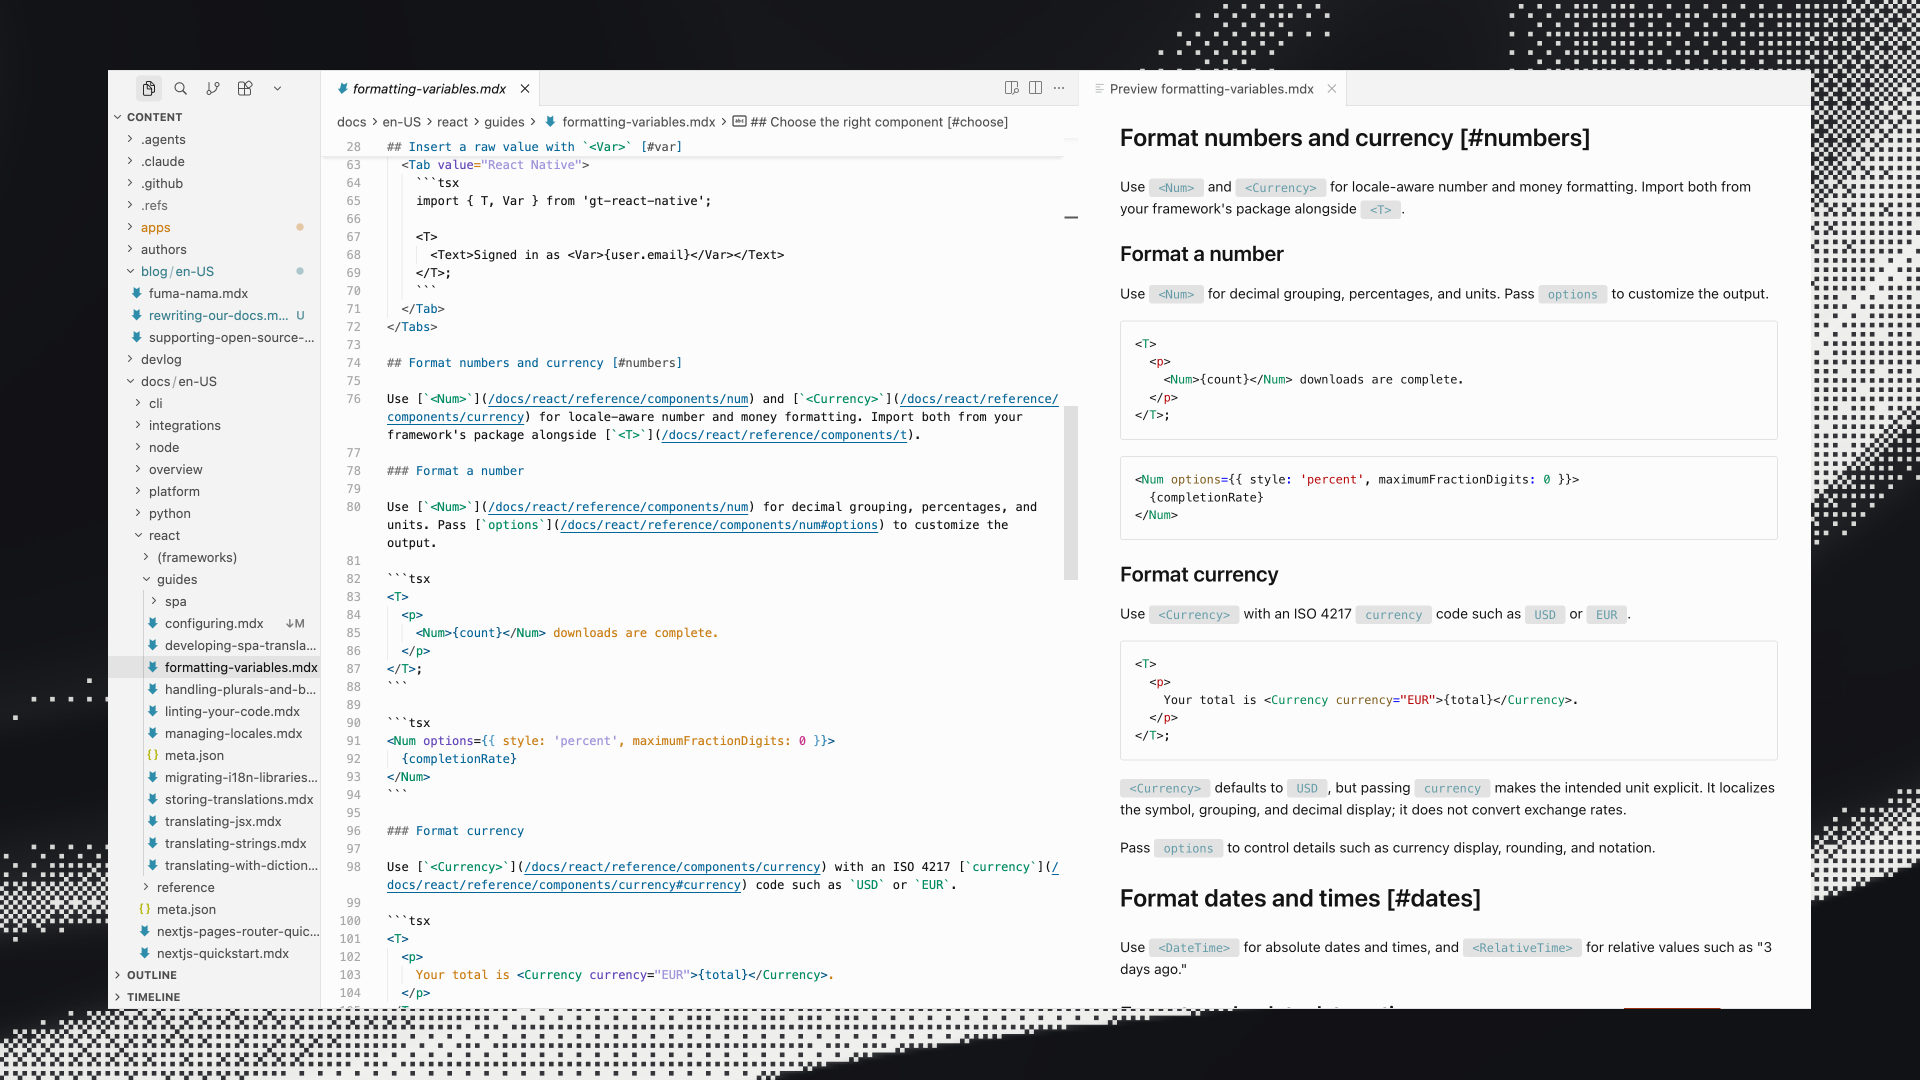
A fascinating part of the process was writing directly in Cursor, making good use of the Markdown preview panel. This meant my exact changes were tracked with version history, so I could then easily ask an agent to generalise my changes (and even thought process) into guidelines and rules, add them to our docs style guide, and apply them across every page. Every time we make edits to our docs, whether in structure or content, we generalise and apply these changes with the style guide.
This process means our docs style guide is extremely detailed and specific to our exact docs preferences, covering a variety of edge cases and user goals, with over 830 lines and 13,000 words. The style guide is a set of operating procedures that are enforced in CI and can easily be applied by agents, covering both meta writing principles as well as very specific rules and skills. A cloud agent also runs daily and syncs docs with shipped behaviour. The agent looks for coverage gaps, inaccuracies, and stale examples. It spins up a fresh project and tests features locally, and also lints prose according to the style guide.
The style guide rules are similar to the context and custom prompt rules we enforce for translation quality for our customers.
Part 2: visual design
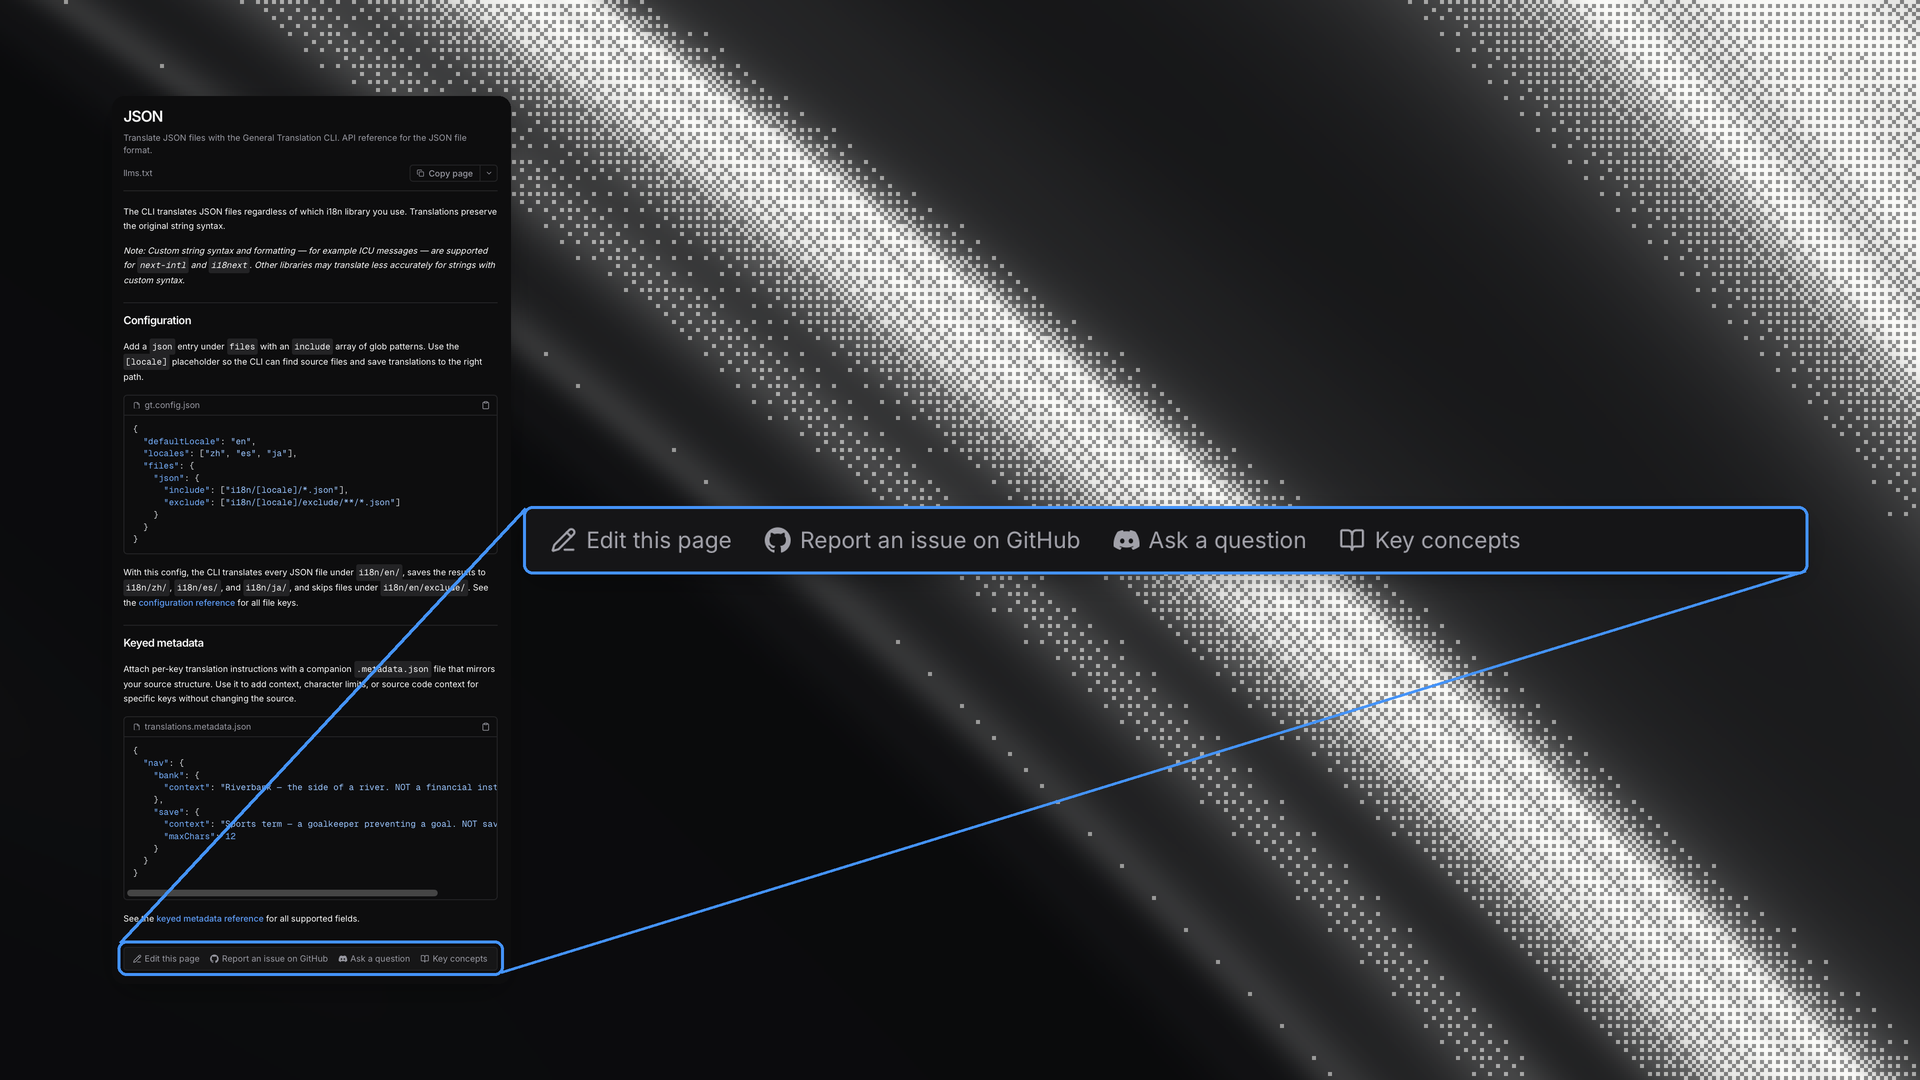
We hope these structural changes have made our docs more intuitive and easy to use. We’d always love to hear your feedback. Every docs page has buttons to edit, report an issue, or ask a question.
Stay tuned for part 2 of our blog, which will cover the UI and interaction redesign of our docs and how we built custom visuals on Fumadocs.